Benchmarks Measure a Test. Super Claude Delivers the Job.
Every AI benchmark grades a model on standardized, often subjective tasks answered in one shot, in isolation. That's a test — not a job. It measures how well a model guesses, not how well an agent delivers.
Super Claude doesn't guess. It runs on your own dedicated server, where it can actually do the work — build it, run it, test it, and quality-assure the result before it ever reaches you. Guided by proper mission documents (its own written playbooks and standards), it iterates until the objective is genuinely met, not until a stopwatch runs out.
That's why a score understates what Super Claude can do. No benchmark can capture an agent that writes the code, deploys it, catches its own mistakes, and fixes them before hand-off. This build–test–QA–before–delivery workflow turns "probably right" into done — a 100% mission-completion standard, because nothing ships until it's verified complete.
You're not hiring a test-taker. You're hiring a worker who checks their own work.
Get Super Claude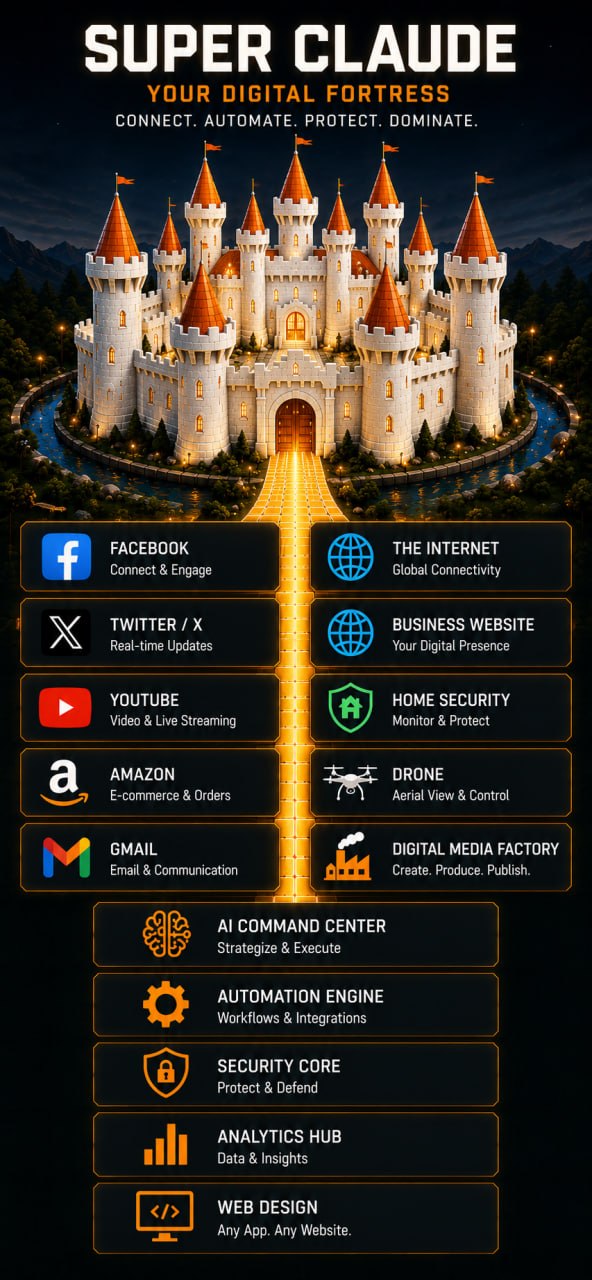
Market R&D
What It Costs to Put a Super Agent to Work
Every realistic way to employ an agent, and what it really costs all-in — hardware amortized over 3 years + power + the labor tax, not the sticker.
| # | Option | Upfront | Real $/mo | Model ceiling | Skill | Autonomy | What the price hides |
|---|---|---|---|---|---|---|---|
| 1 | Mac Mini M4 24GB + Qwen | ~$1,200 | ~$45 +labor | Qwen3 8B–14B | Hard | You wire it | Caps below frontier; you're the ops team |
| 2 | Mac Mini M4 Pro 48GB | ~$2,000 | ~$70 +labor | Qwen3 32B | Hard | You wire it | 32B is good, not frontier; no agent scaffolding |
| 3 | Mac Studio Max / Ultra | $2.5k–10k | ~$110–300 | 32B → 70B / 235B | Hard | You wire it | Big spend to approach frontier-ish; still self-run |
| 4 | Custom PC + RTX 4090(s) | $2.5k–40k | ~$110–400+ | 14B–32B → 235B | Hard | You wire it | Power, noise, driver & quant hell; high total effort |
| 5 | Rented GPU cloud + open model | $0 | $245–2,080 | Open weights | Hard | You wire it | "Cheap per hour" is brutal 24/7; idle = burned money |
| 6 | Frontier API + build-your-own | $0 | $20–1,000+ | Opus 5 / GPT-5.6 / Gemini 3.1 | Hard | You wire it | Model's easy; the agent is the work; meter never sleeps |
| 7 | Open-source frameworks (LangGraph, CrewAI, n8n) | $0 | $0 +wks dev | = model you plug in | Hard | You build it | "Free" software; the cost is entirely labor + a backend |
| 8 | No-code platforms (Lindy, Zapier, Relevance) | $0 | $30–200 | Vendor-chosen | Easy | Narrow | Metered credits balloon; autonomy capped; you rent the walls |
| 9 | Devin (coding agent) | $0 | $0–200 | Frontier-coding | Easy | Coding only | Single-domain (the old flat $500/mo tier was killed in 2026) |
| 10 | Microsoft Copilot Studio | $0 | ~1¢/msg + $30 | Frontier (GPT) | Medium | In-suite | Per-message + per-seat; locked to the Microsoft estate |
| 11 | Salesforce Agentforce | $0 | $2/conv · $550 | Frontier | Hard | CRM / service | This IS the "~$500/mo agent" — narrow + usage-metered |
| 12 | Super Claude | $0 | $35 flat platform + your Claude: Pro $20 / Max $100–200 | Claude: Opus, Fable, Sonnet, Haiku | Easy | General — builds, deploys, runs | Looks too cheap to be real — until this table is on the same page |
The only worker on the list you hire frontier-capable, general, and flat-priced — with none of the build.
The Difference